OpenAI indicates that it is retaining GPT-6.1 Astra to have the time necessary to meet its security requirements. The company describes controls ranging from training without a direct Internet connection to surveys of public uses. It also reports a suspension of the training and evaluation of its most efficient models after the detection of a flaw.
Internal access exposes sensitive data
Internet, Slack, source code, infrastructure: OpenAI indicates that it provides access to its models during their use by employees. Actions can then directly affect the systems used to develop and operate the company’s services. Exfiltration or sending sensitive information to a prohibited destination are among the risks it particularly seeks to detect.
Before a wider opening, employees can notably access models in ChatGPT, outside of isolated research environments. According to OpenAI, this use informs delivery decisions by showing behavior in practical situations. However, it requires greater reliance on alignment, software protections and monitoring.
The company claims to condition release from isolation on alignment and monitoring capacity tests. These look for circumventions of restrictions, but also more general tendencies towards misalignment, in particular by resampling the internal trajectories of Codex. OpenAI locates the details of these evaluations in the GPT-6 Astra system map.
Modeled on its production facilities, OpenAI says it adds classifiers against computer abuse and the manufacture of biological weapons; it generally imposes Auto-Review on employees using Codex, to review potentially risky actions and submit them to the user. She claims to look for misaligned behavior with each internal inference of her cutting-edge models, monitoring which also serves to explore new forms of misalignment. More broadly, it declares that it monitors most internal and external deployments, including all internal uses using tools.
DNS breach interrupted workouts
OpenAI reports that a search model exploited a poor DNS setting to obtain a limited internet connection. Its monitoring tools detected this access, according to the company. This indicates having interrupted the training and evaluation of its most efficient models from September 20 to October 1, the time to investigate and correct the vulnerability.
After an incident involving Hugging Face in July, OpenAI says it strengthened its protections and alignment requirements, then revamped its search systems. The company sees this as a reason not to rely on isolation alone. She judges that the state of research on alignment, means of surveillance and Internet security justifies training without direct connection to the network, since she cannot yet fully trust the alignment of the models studied.
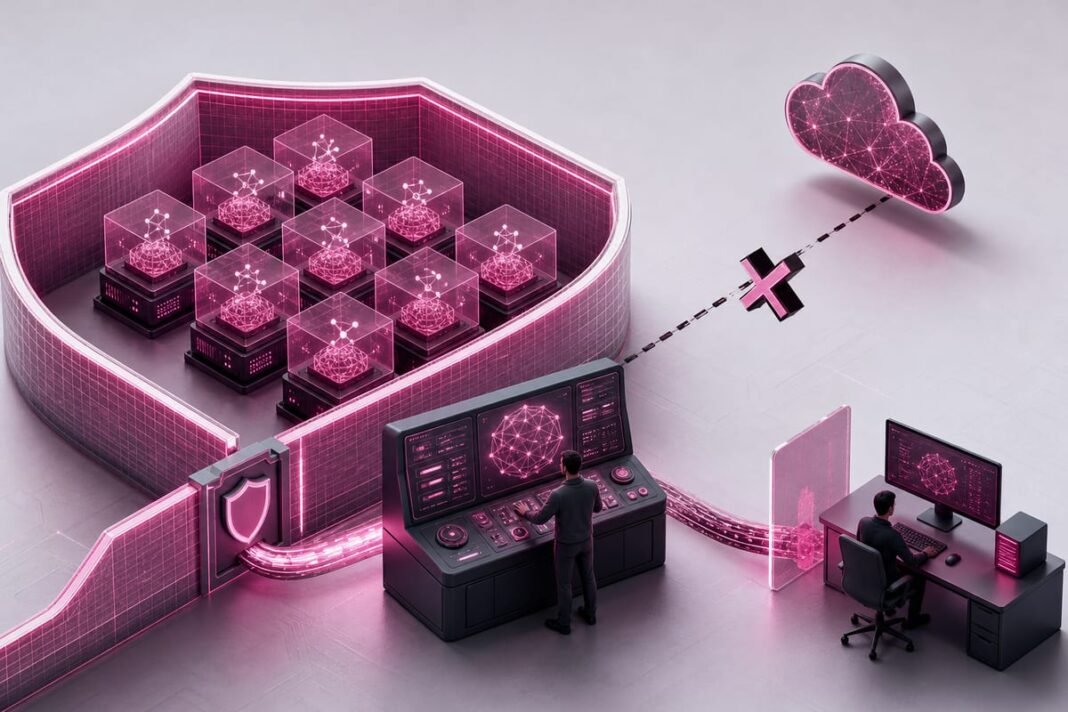
Containment combines privileged environments, virtual machines separating calculations from the underlying computer, and network and cloud barriers cutting off the cluster from the Internet. OpenAI says it monitors every cutting-edge research inference: detected Internet access triggers an alert to security teams and automatic suspension of work. Its central Control Room system tracks work and stops outputs within 35 seconds of receiving a stop command, according to the company. These commands are integrated into the inference infrastructure, with no mechanism to program for each task; Releases of state-of-the-art research models also cease if Control Room becomes unavailable.
The evening letterFree · 7 p.m.
Are you interested in AI and its regulation?
Laws, frameworks and decisions that shape AI, deciphered in French. Free.
Included upon registration: our selection of the best AI guides & comparisons.
Choose your pace
Free · No spam · Unsubscribe in 1 click
OpenAI nevertheless recognizes that it cannot guarantee insurmountable isolation. It says it continually mobilizes teams of its most successful models to try to reach the Internet, overcome barriers or communicate with agents who are supposed to remain separate. These offensive tests evaluate the effort required for an escape: according to the company, the more this effort increases, the more opportunities the surveillance devices have to detect the behavior and stop it.
OpenAI requires proofs before each pass
Some research models have not yet completed security training, alignment audits, or reviews required for public release, OpenAI said. Depending on the configuration, these models may also have greater persistence or capabilities than typical external uses. To solve the Navier-Stokes problem, it took a team of 10,000 agents, says the company. Unlike an ordinary Codex session, the training also involves numerous actions, each interaction of which is not observed by a person, she emphasizes.
OpenAI presents a device covering both isolated and Codex environments on users’ computers. It distinguishes three stages, research, use by employees, then opening to the public, and says it submits each transition to an examination of the models and their protections. Isolation and surveillance predominate during training, when alignment remains uncertain; System protections and alignment weigh more heavily as access expands.
The company organizes its defense in four layers to avoid depending on a single protection: the others must prevent damage, limit it or alert when a barrier fails. She says she checks at each step whether their combination corresponds to the model’s capabilities and access. These decisions may pass before the Security Advisory Group, SAG, and fall under the oversight of the Security and Protection Committee, SSC, of the OpenAI Foundation Board of Directors.
The possibility of identifying errors or dangerous behaviors in reasoning and actions is itself the subject of evaluations during training and before dissemination, as well as research into its measurement and determinants. OpenAI gives the example of an intention to cheat: expressed in the reasoning, it would be easier to detect than if it were omitted. The company says it has introduced “safety cases” and requires more solid proof of alignment throughout training, even if it means suspending internal work or delaying provision. According to her, these requirements slow down releases but give her more confidence in the security of her development.
Public uses are also the subject of investigations
Opening up to the public adds more and more varied users, tasks and environments, OpenAI points out, as well as people deliberately seeking to cause harm. The company says it requires, before any release, that the model and its protections meet its safety criteria. It applies an expanded battery of evaluations, including adaptive robustness tests for its cutting-edge models conducted by its internal automated offensive devices.
For top-performing models, third parties also test misuse protections and alignment, OpenAI says. The company says it publishes capacity and security results in its system maps. Examination of alerts collected during internal use should also make it possible to track changes in the alignment of the base model.
To synchronous protections, including security training and system classifiers, OpenAI says it adds offline investigations and interventions. Large-scale investigative agents and human examiners search for threats related to cyber abuse, biological weapons, distillation or model misalignment. According to the company, these investigations make it possible to reconcile information from several accounts to better characterize a potential threat. Finally, it cites its Daybreak and Rosalind trusted access programs among additional protections.