Published scripts and containers allow TRELLIS.2 to be refined with LoRA, locally or via Hugging Face Jobs. The method targets structure and geometry, with concrete figures: 16 views per object and approximately one hour for 188 meshes on a100-large. Datasets can be pushed and reused on the Hub.
A measured flow: 16 views per object and one hour for 188 models
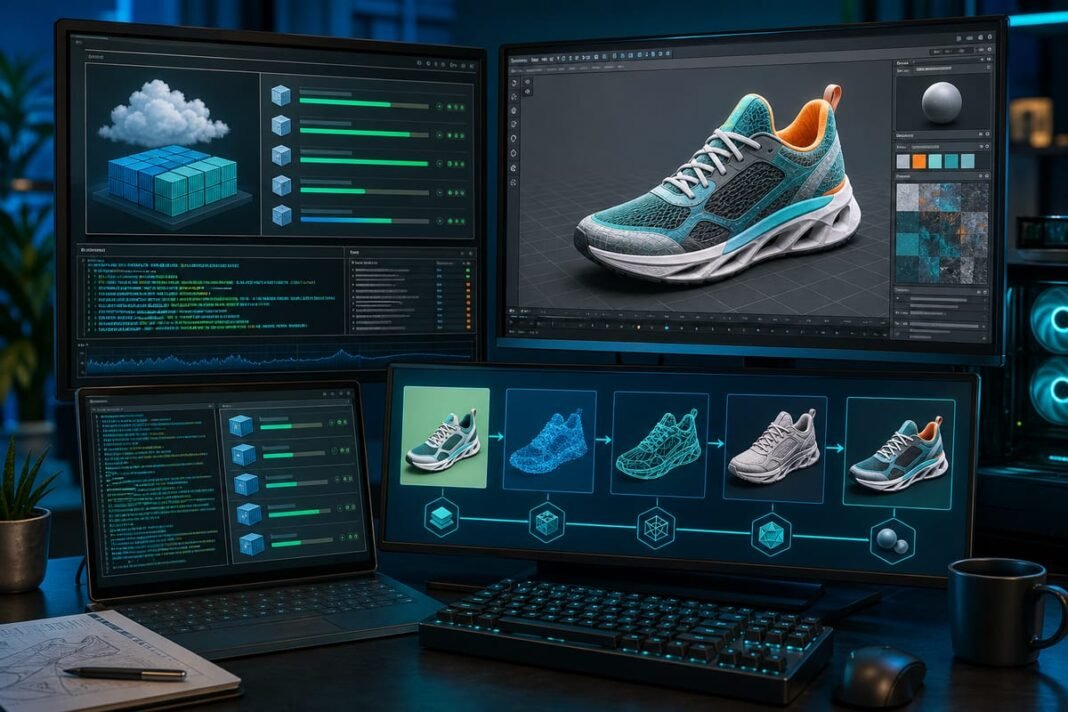
Preprocessing generates 16 views of each object using Blender, which then serve as conditioning images for LoRA training. On an a100-large job, preparing a batch of 188 objects took about an hour. The hardware is specified with the argument –flavor a100-large, corresponding to an 80 GB card. Parameters include a timeout of 6h, the options –holdout 0.05, –views 16 and –workers 8, and publishing output to a Hub repository. In detached mode, the tool displays the job ID and URL, and the logs are accessible via the dedicated command.
What’s delivered: Two Docker images and a four-step path
Ready-to-use scripts and containers allow you to fine-tune TRELLIS.2 locally or on Hugging Face Jobs. Two Docker images are offered: one for preprocessing, the other for fine-tuning. The recommended procedure consists of four actions: give access to the data to the containers, set the task parameters, execute the preprocessing image then the training image. The preprocessed dataset is saved for reusability in subsequent sessions.
Target shape: LoRA on two DiTs and not on texture
LoRA adapters are applied only to the DiT sparse structure stream and the DiT shape stream, which determine the shape and geometry of the object. The DiT texture stream is frozen to maintain its current capabilities. The dataset used has diffuse color maps but no separate material maps, the former mixing surface color and illumination; therefore they are not correct targets for training the texture. Inadequate training could cause the model to confuse lighting and material and cause catastrophic forgetting. On a subset of 188 shoes, initial testing showed incorrect soles with the pre-trained model; a LoRA is tested to improve this point, while the colors and textures of the base model are considered satisfactory.
The papers and advances that matter, explained simply, every evening. Free.
Included upon registration: our selection of the best AI guides & comparisons.
Choose your pace
Free · No spam · Unsubscribe in 1 click
LoRA settings: approximately 9.3 million settings in total
The presented configuration results in a total of approximately 9.3 million adapter parameters for all of the two DiTs involved. Rank 8 modules are placed in the attention and MLP layers of the DiT dedicated to the structure, while rank 16 modules are used in the attention layers of the shape DiT. The rank determines the size of the adapter matrices and a higher rank increases their learning capacity. With 188 shoes from 1,030 GSO objects, LoRA is favored over complete fine-tuning, considered much more expensive and likely to overwrite useful knowledge of the model.
Under the hood: five stages, O-Voxel and sparse transformers
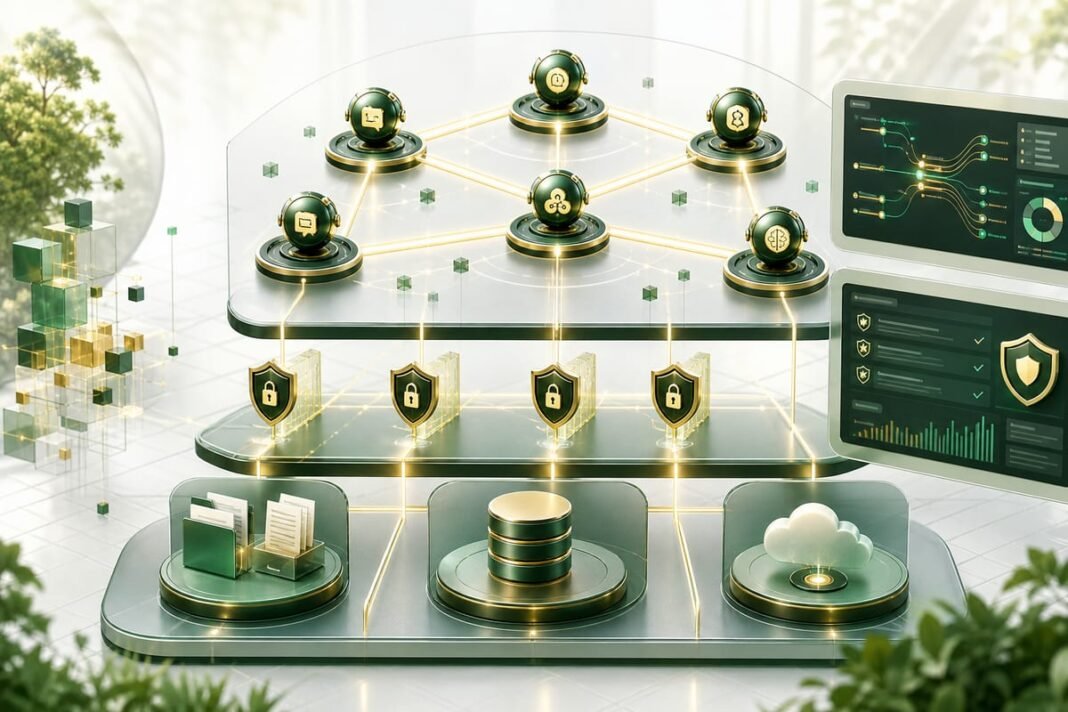
The TRELLIS.2 pipeline follows five steps: background removal by BiRefNet, image encoding into tokens by DINOv3-L, prediction of a coarse structure, generation of detailed geometry, then definition of materials before exporting a textured mesh. The structure flow generates a 16³ × 8 latent, decoded into a 64 × 64 × 64 occupancy grid; LoRAs are added to influence the geometry. The O-Voxel representation retains only surface voxels and stores local geometry and material attributes; a CPU converts a mesh into an O-Voxel in a few seconds and the reverse operation is carried out in a few seconds on GPU. Inherited from TRELLIS, the sparse structured latents only use around 10% of the voxels, and the shape and texture flows rely on sparse transformers, when the structure flow is dense. O-Voxel geometry is produced at a resolution of 512 × 512 × 512; LoRAs are also added to the form DiT. Materials are then defined and decoded into base color, metallic, roughness and alpha maps, without LoRA at this stage, before exporting a GLB. TRELLIS.2 follows in the footsteps of TRELLIS, which introduces a unified latent representation converted by decoders, avoiding models per format. The stated objective is to improve performance on a specific category of objects by refining only the relevant components.
Scripts run on local GPU or via Hugging Face Jobs
Loads run on Hugging Face Jobs, used for preprocessing and training, or via Docker on a local GPU. An HF_TOKEN token is required and access to the DINOv3 restricted model must be granted to the account. Personal datasets must be pushed to the Hub before starting. Two Docker images embed dependencies to avoid lengthy installations, respectively for preprocessing and fine-tuning. On Jobs, the token is passed as an encrypted variable without being written to the image; the URI cr.hf.co/…:latest designates the image, followed by the executed command. Other arguments are supported, including local execution. The typical approach consists of three parts: convert GLB or OBJ meshes and render the input images, launch a training by DiT with LoRA configuration, then rely on the containerized code to load the data, insert the adapters and train the models.